Prerequisites
- Set up the QAIRT SDK on your host computer. For detailed installation and configuration instructions, see Set up Qualcomm AI Runtime SDK.
- Select the model for profiling. You can either convert and quantize a custom model using QAIRT tools or generate a quantized model through AI Hub. For detailed guidance on compiling and optimizing models, see Compile and optimize an AI model. The following instructions use the Inception V3 model from AI Hub.
- Enable Wi-Fi and SSH on the device. The device requires an internet connection to download the artifacts needed to run sample applications. If SSH and Wi-Fi are already configured, skip this step. Follow Setup an SSH connection to enable Wi-Fi and SSH on the device.
-
Ensure that you have installed the following QNN tools on the target device as part of the build.
- qnn-net-run
- qnn-throughput-net-run
- qnn-context-binary-generator
- qnn-profile-viewer
Profiling levels on HTP
The following table provides the profiling levels, their description, and configuration:
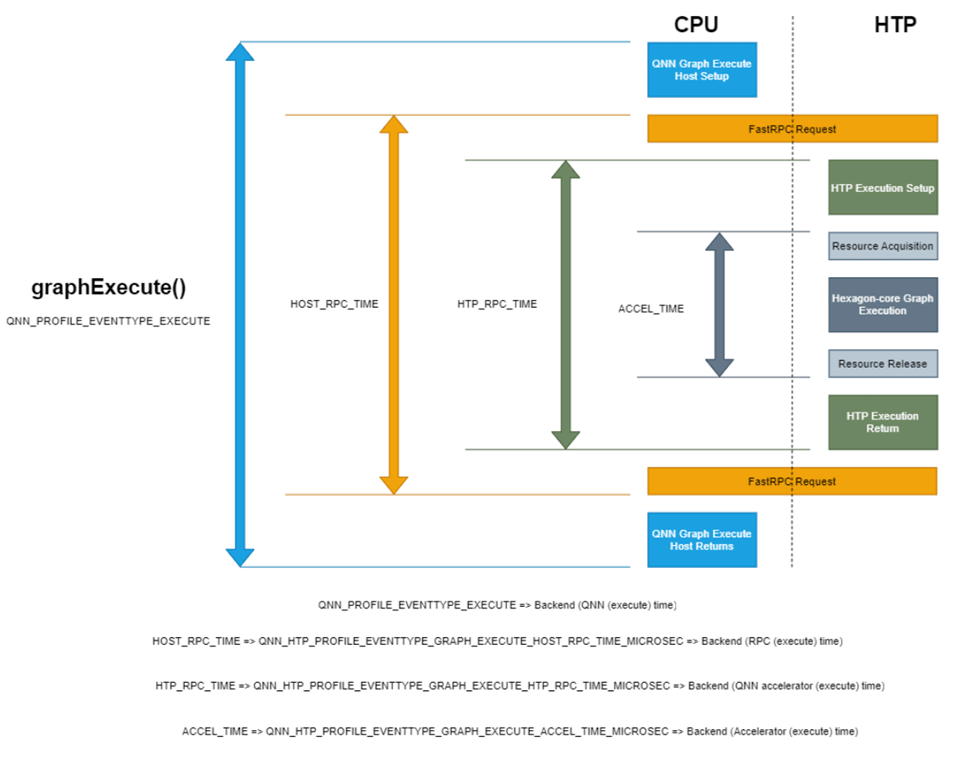
The following figure shows the primary execution profiling events for HTP and how these events are measured during inference:
Perform Lint profile with qnn-net-run
Lint profiling provides detailed per-operation cycle counts on the main thread along with background execution information. The following steps perform lint profiling on the Inception-v3 AI Hub model. Follow these steps and replace the model with your custom model.
1
SSH into the target device
oelinux123 as the password.2
Download the quantized Inception V3 model
Download the quantized (w8a8) inception_v3 dlc model from AI Hub on the target
device for profiling.
3
Generate input files for profiling
For demonstration purposes, you can profile the model using generated input files.Generate these input files using the following Python script tailored for the
inception_v3_quantized.dlc model.1
Create the input-generation script
Create the directory:Save the following script as This script generates 10 sample input files saved in the
generate_random_input.py in the ${HOME}/models directory./tmp/RandomInputsForInceptionV3Profiling/
directory and an input_list_profiling.txt file that contains the path to each sample generated.2
Run the input-generation script
Run the script on the target device:
4
Create the HTP configuration files
Create the
backend_extension_config_file.json and htp_config.json files in the ${HOME}/models directory
of the target device to profile the model using the HTP runtime.-
backend_extension_config_file.json -
htp_config.json- Use
"dsp_arch": "v68"for Qualcomm Dragonwing™ RB3 Gen 2 - Use
"dsp_arch": "v75"for Dragonwing IQ-8275 - Use
"dsp_arch": "v73"for Dragonwing IQ-9075 - Use
"dsp_arch": "v73"for Dragonwing IQX-7181 - Use
"dsp_arch": "v73"for Dragonwing IQX-5121
- Use
5
Run qnn-net-run
Go to the
${HOME}/models directory and run the qnn-net-run command on the target device:6
Verify lint profiling output
Enable lint profiling by specifying 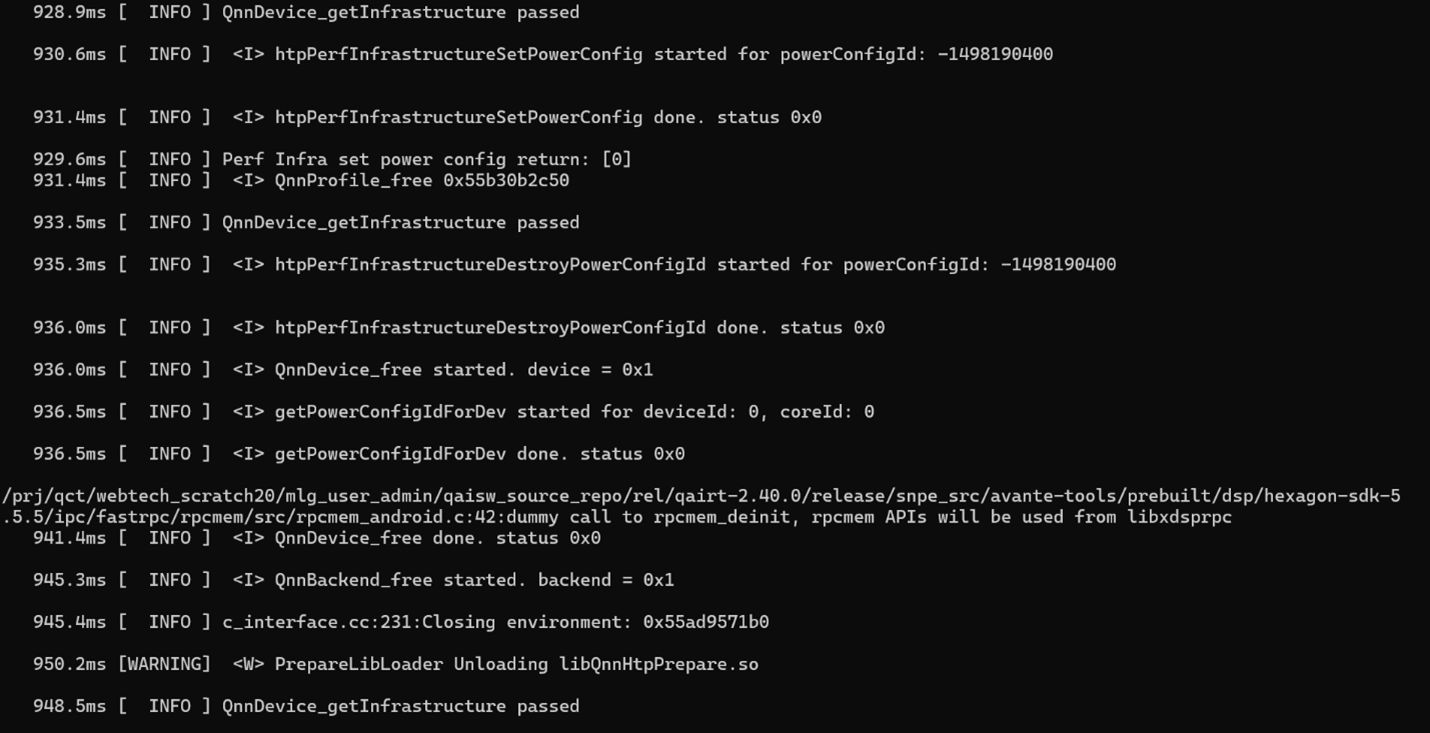
--profiling_level=backend. This step ensures that the profiling level defined in the backend-specific configuration file is applied.The execution_metadata.yaml and qnn-profiling-data_0.log files should be created in the ${HOME}/models/output_htp directory.To view logs from the qnn-profiling-data_0.log file, use qnn-profile-viewer.View lint profiling logs using qnn-profile-viewer
View the profile outputs generated at the backend profiling level by using the qnn-profile-viewer tool with the following plugins:- libQnnHtpProfilingReader.so
- libQnnChrometraceProfilingReader.so
To retrieve linting information from an inference, run qnn-profile-viewer with the The following is the sample output: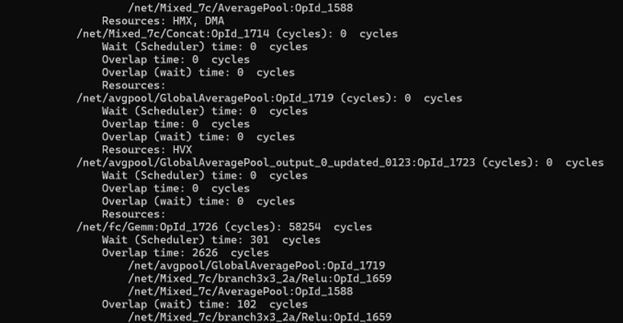
libQnnHtpProfilingReader.so plugin. This plugin provides raw output of every single run.- Cycle count: the time spent executing on the main thread.
- Wait entry: the cycles spent waiting before execution starts.
- Overlap: the cycles spent on at least one background operation while the main thread executes the current operation.
- Overlap (wait): the cycles spent on at least one background operation during the main thread’s wait period.
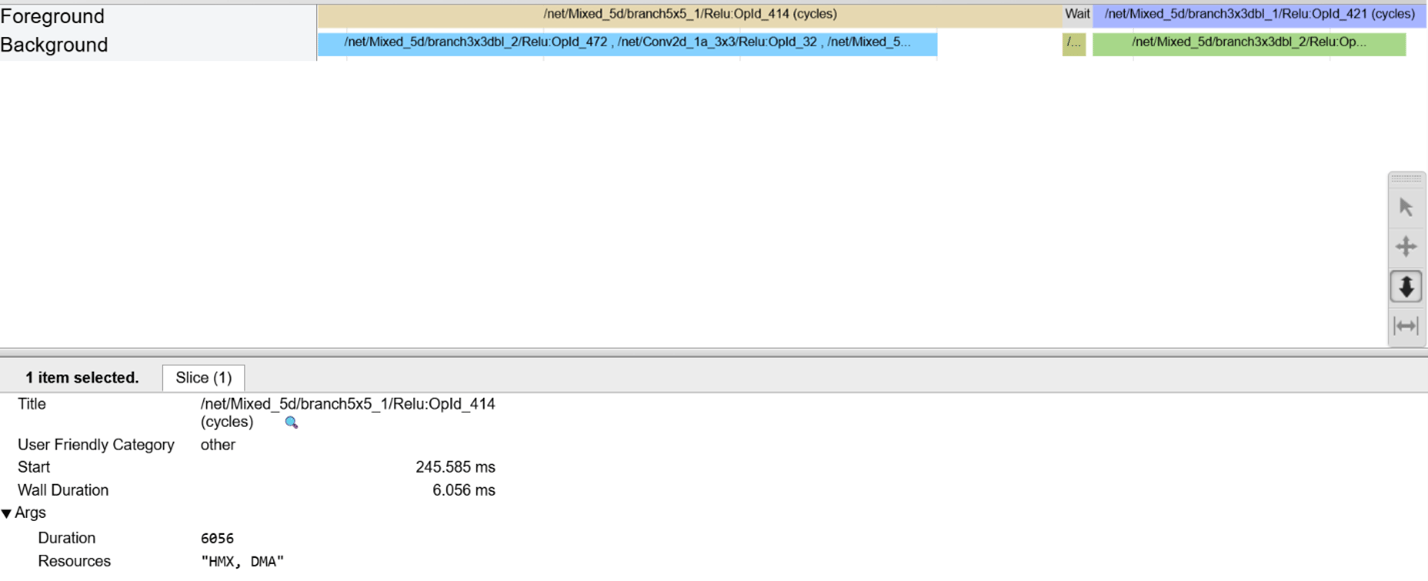
Every operation on the main thread has a wait period before its executed, which only begins once the previous operation has ended. This delay may be caused by scheduling issues or by waiting for background activities like HVX or DMA to finish.
Perform advanced profiling with QNN HTP Optrace
Use QNN optrace profiling to understand detailed internal operations of QNN HTP hardware blocks. This capability helps you:- Identify problematic operations that may not be parallelized well.
- See how operations are scheduled throughout execution.
- Observe the interaction between various operators.
- Evaluate how efficiently HVX parallelism works for each operation.
Perform profiling with qnn-throughput-net-run
Use qnn-throughput-net-run for multi-threaded execution across one or more QNN backends. This profiling supports multi-threaded execution and lets you run models repeatedly for a specified duration or a set number of iterations. Use this profiling for scenarios where you need concurrent or repeated execution of multiple models for performance benchmarking.
1
SSH into the target device
oelinux123 as the password.2
Create a working directory
On the target device, create a working directory.
3
Download the quantized Inception V3 model
On the target device, download the quantized (w8a8) inception_v3 dlc model from AI Hub.
4
Create the HTP configuration files
On the target device, create the
backend_extension_config.json and htp_config.json files in the ${HOME}/models directory.These files are required to generate the context binary in the next step.- backend_extension_config.json
- htp_config.json
- Use
"dsp_arch": "v68"for Qualcomm Dragonwing™ RB3 Gen 2. - Use
"dsp_arch": "v75"for Dragonwing IQ-8275. - Use
"dsp_arch": "v73"for Dragonwing IQ-9075.
5
Generate the context binary
On the target device, generate the context binary (.bin file) using the qnn-context-binary-generator tool.The
qnn-throughput-net-run command will ingest the generated context binary.6
Create qnn-throughput-net-run configuration files
To profile the model using
qnn-throughput-net-run, create the qtnr_config.json and
htp_backend.json files in the ${HOME}/models/ directory on the target device.htp_backend.json:
qtnr_config.json:
- Use
"dsp_arch":"v68"for Qualcomm Dragonwing™ RB3 Gen 2 - Use
"dsp_arch":"v75"for Dragonwing IQ-8275 - Use
"dsp_arch":"v73"for Dragonwing IQ-9075
7
Run throughput profiling
To perform profiling, on the target device, run the following commands:The profiling information is generated in the 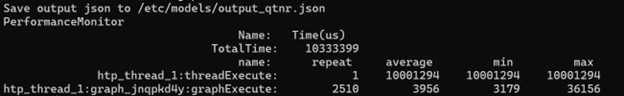
${HOME}/models directory.