> ## Documentation Index
> Fetch the complete documentation index at: https://dragonwingdocs-staging.qualcomm.com/llms.txt
> Use this file to discover all available pages before exploring further.
# Deploy a LiteRT model
> Deploy LiteRT models using the label_image sample application, C++ APIs, or the Qualcomm IM SDK.
You can run LiteRT models on Qualcomm development kits using the precompiled `label_image` sample application, the LiteRT C++ APIs, or the Qualcomm IM SDK `gst-ai-classification` pipeline.
Before deploying, ensure you have completed the [prerequisites and model setup](../topic/benchmark-a-litert-model#prerequisites).
## Deploy as a native application
The `label_image` sample application is part of the TensorFlow repository and is cross-compiled with the LiteRT library and installed on the target device. It loads a classification LiteRT model and performs inference on an image using a delegate.
**Run on CPU using the XNNPACK delegate:**
```shell theme={null}
label_image -l ${HOME}/artifacts/labels.txt \
-i ${HOME}/artifacts/grace_hopper.bmp \
-m ${HOME}/artifacts/mobilenet_v1_1.0_224_quant.tflite \
-c 10 \
-p 1 \
--xnnpack_delegate 1
```
**Run on GPU using the GPU delegate:**
```shell theme={null}
label_image -l ${HOME}/artifacts/labels.txt \
-i ${HOME}/artifacts/grace_hopper.bmp \
-m ${HOME}/artifacts/mobilenet_v1_1.0_224.tflite \
-c 10 \
-p 1 \
--gl_backend 1
```
For the source code, see the [label\_image example](https://github.com/tensorflow/tensorflow/tree/master/tensorflow/lite/examples/label_image) on the TensorFlow GitHub repository.
## Deploy as a C++ application
The following figure shows the steps involved in creating a C++ application to run a LiteRT model:
 ### Load a LiteRT model
A LiteRT model is a FlatBuffers file containing model operators, weights, and biases. Use the following API to load a model for inference:
```cpp theme={null}
#include
#include
#include "tensorflow/lite/interpreter.h"
#include "tensorflow/lite/kernels/register.h"
#include "tensorflow/lite/model.h"
#include "tensorflow/lite/optional_debug_tools.h"
std::unique_ptr model;
model = tflite::FlatBufferModel::BuildFromFile(model_name.c_str());
if (!model) {
std::cerr << "Failed to mmap model " << model_name << std::endl;
exit(-1);
}
```
### Create a LiteRT interpreter
The interpreter configures model execution on a chosen delegate and allocates memory for forward propagation:
```cpp theme={null}
tflite::ops::builtin::BuiltinOpResolver resolver;
tflite::InterpreterBuilder builder(*model, resolver);
std::unique_ptr interpreter;
builder(&interpreter);
if (!interpreter) {
std::cerr << "Failed to construct interpreter on provided tflite model" << std::endl;
}
if (interpreter->AllocateTensors() != kTfLiteOk) {
std::cerr << "Failed to allocate tensors!" << std::endl;
exit(-1);
}
```
### Prepare the model with a delegate
The following example creates the XNNPACK delegate for running a LiteRT model on the Arm® CPU:
```cpp theme={null}
TfLiteXNNPackDelegateOptions xnnpack_options = TfLiteXNNPackDelegateOptionsDefault();
xnnpack_options.num_threads = num_threads;
TfLiteDelegate* xnnpack_delegate = TfLiteXNNPackDelegateCreate(&xnnpack_options);
if (interpreter->ModifyGraphWithDelegate(xnnpack_delegate) != kTfLiteOk) {
// Report error and fall back to another delegate, or the default backend
}
```
### Prepare input/output buffers
Before running inference, preprocess the input data (such as camera frames) to match the model's expected format. Common preprocessing steps include:
* Resizing the input image to the resolution expected by the model
* Normalization
* Mean subtraction
### Run inference
Use the `Invoke()` API to run inference. After completion, parse the output tensors from the interpreter:
```cpp theme={null}
interpreter->Invoke();
```
For a comprehensive example, see the [label\_image example on the TensorFlow GitHub repository](https://github.com/tensorflow/tensorflow/tree/master/tensorflow/lite/examples/label_image).
For more information, see the [LiteRT documentation](https://ai.google.dev/edge/litert).
## Deploy with the Qualcomm IM SDK
The `gst-ai-classification` sample application uses the Qualcomm IM SDK plugins to run a LiteRT classification model on Qualcomm development kits with hardware acceleration.
The pipeline receives a video stream from a camera, performs preprocessing, runs inference on the AI hardware, and displays the results:
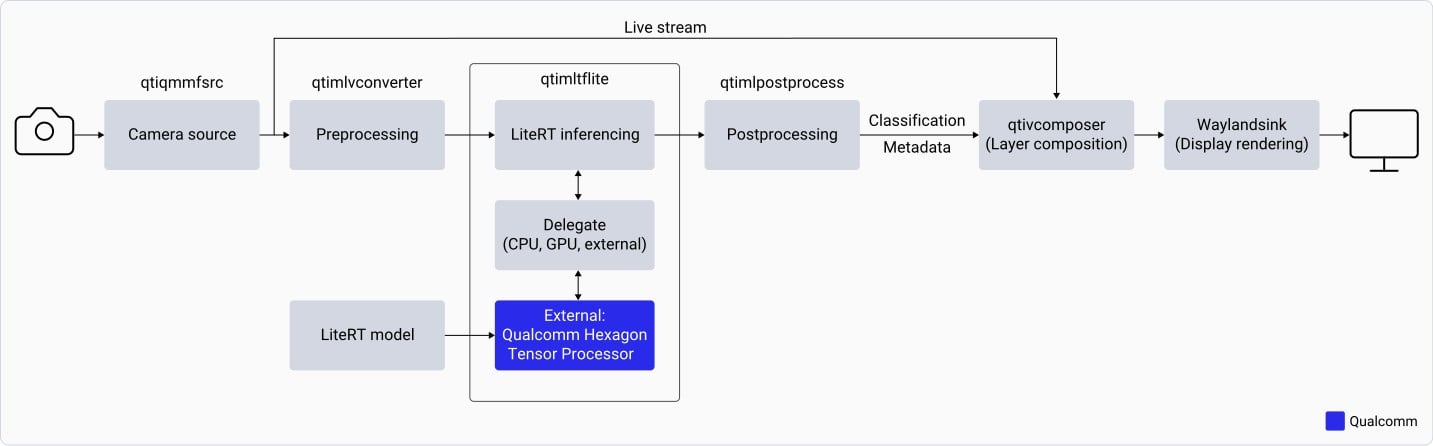 The `gst-ai-classification` application:
1. Opens the IMX577 camera at a specified resolution and frame rate (for example, 1080p at 30 fps).
2. Preprocesses each camera frame — downscales to 224×224 and normalizes based on model requirements.
3. Loads the LiteRT classification model and runs inference using the `qtimltflite` plugin.
4. Extracts the label with the highest predicted probability from the output tensor.
5. Overlays the inference result on the original camera frame and displays it on the connected monitor.
`camera` use-case is not supported on `IQ-2390`.
### Download the model and label files
Go to [Qualcomm AI Hub](https://aihub.qualcomm.com/models/inception_v3?searchTerm=ince\&chipsets=qualcomm-qcs6490-proxy) and download the Inception-v3 quantized model.
```shell theme={null}
curl -L -O https://raw.githubusercontent.com/qualcomm/sample-apps-for-qualcomm-linux/refs/heads/main/artifacts/json_labels/classification.json
```
```shell theme={null}
ssh root@
```
```shell theme={null}
mkdir -p ${HOME}/Downloads/qimsdk_samples/models ${HOME}/Downloads/qimsdk_samples/labels ${HOME}/Downloads/qimsdk_samples/media
```
```shell theme={null}
exit
```
```shell theme={null}
scp classification.json root@:~/Downloads/qimsdk_samples/labels
```
```shell theme={null}
scp inception_v3-inception-v3-w8a8.tflite root@:~/Downloads/qimsdk_samples/models/inception_v3_quantized.tflite
```
### Run the sample application
```shell theme={null}
ssh root@
```
Download the [video file](https://github.com/qualcomm/sample-apps-for-qualcomm-linux/raw/refs/heads/main/qualcomm-linux/artifacts/videos/video.mp4) to `/etc/media/video.mp4` on the device:
```shell theme={null}
wget -O ${HOME}/Downloads/qimsdk_samples/media/video.mp4 https://github.com/qualcomm/sample-apps-for-qualcomm-linux/raw/refs/heads/main/qualcomm-linux/artifacts/videos/video.mp4
```
```shell theme={null}
gst-ai-classification --config-file=/etc/configs/config_classification.json
```
This command runs the application using the sample configuration in `/etc/configs/config_classification.json`.
To stop the application, press `Ctrl+C`.
You can use a custom configuration file by specifying its path with `--config-file`:
```bash theme={null}
gst-ai-classification --config-file=/path/to/config_classification.json
```
If `--config-file` is specified, the application uses that file. Otherwise, it searches for `config_classification.json` in the following order:
| Priority | Location | Description |
| :-: | :- | :- |
| 1 | The path provided with `--config-file`. | Uses the configuration file specified on the command line. |
| 2 | `$XDG_CONFIG_HOME/qimsdk_samples/config_classification.json` | Uses the user-defined configuration directory when the environment variable is set. |
| 3 | `$HOME/.config/qimsdk_samples/config_classification.json` | Uses the default user configuration directory when no file is found in `XDG_CONFIG_HOME`. |
| 4 | `/etc/configs/config_classification.json` | Uses the system-wide configuration file as the final fallback. |
To create a user-specific configuration, copy the sample file to the user configuration directory:
```bash theme={null}
export XDG_CONFIG_HOME="$HOME/.config"
mkdir -p "$XDG_CONFIG_HOME/qimsdk_samples"
cp /etc/configs/config_classification.json "$XDG_CONFIG_HOME/qimsdk_samples/config_classification.json"
```
To view the available command-line options, run:
```bash theme={null}
gst-ai-classification -h
```
Edit the `config_classification.json` configuration file:
```json theme={null}
{
"file-path": "video.mp4",
"ml-framework": "tflite",
"model": "inception_v3_quantized.tflite",
"labels": "classification.json",
"threshold": 40,
"runtime": "dsp",
"output-type": "waylandsink"
}
```
The application uses `$HOME/Downloads/qimsdk_samples` as its artifact directory. When a relative path or filename is specified, it is resolved against the corresponding subdirectory below. Alternatively, absolute paths are used as provided.
| Configuration field | Resolution of a relative path |
| :- | :- |
| `file-path` | `$HOME/Downloads/qimsdk_samples/media/video.mp4` |
| `model` | `$HOME/Downloads/qimsdk_samples/models/inception_v3_quantized.tflite` |
| `labels` | `$HOME/Downloads/qimsdk_samples/labels/classification.json` |
Run the application:
```bash theme={null}
gst-ai-classification
```
When running, the application displays the video stream on the connected monitor with inference results overlaid on each frame.